In the last article, every input and every memory had size one. In this article, we grow them. The hidden size, h, is how many numbers the hidden state holds. The input size, d, is how many numbers each step reads. We also read a batch, several sequences at once. Within this article, we keep the weights fixed, so each example differs from the last in one way only.
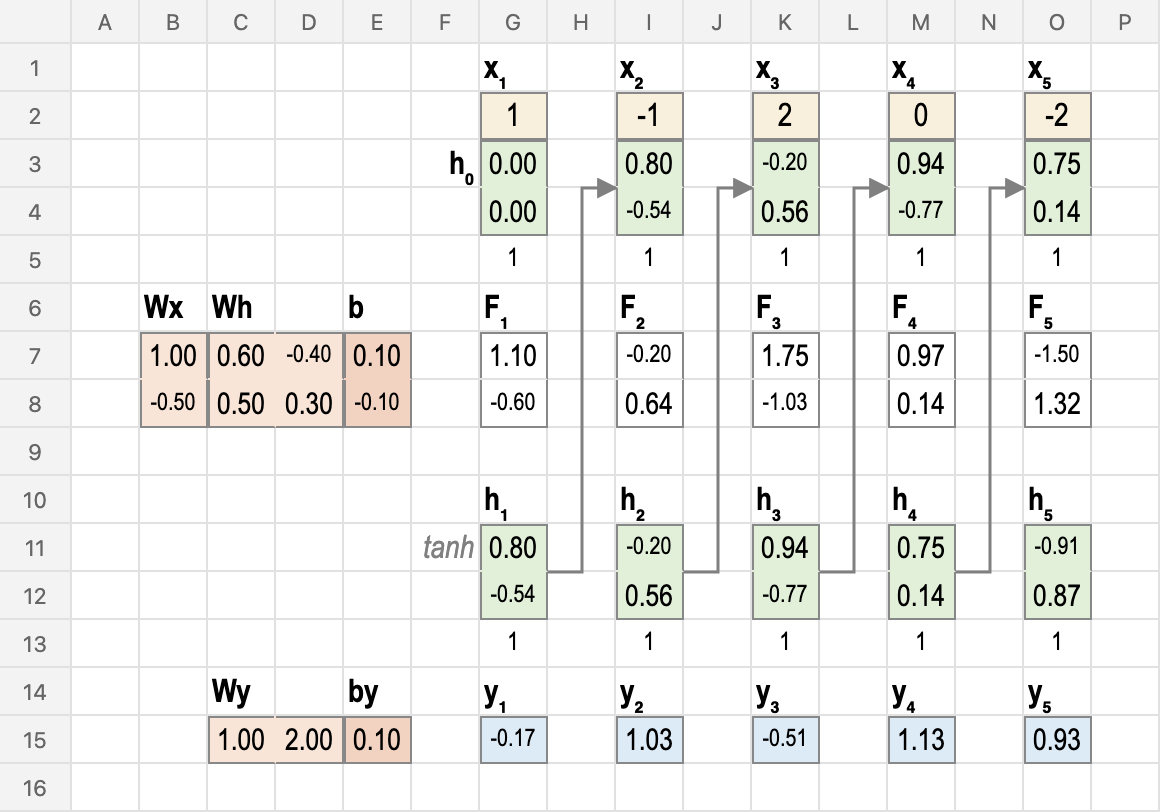
d=1, h=2, seq=5
We give the memory a second number, in green. Every step still does the same thing. At step t, it reads its input xₜ and the hidden state from the step before, hₜ₋₁. What grows is the weights. Wx, b and Wy each gain an entry, one per memory number. Wh becomes a matrix. Why a matrix? Because each new memory number reads both old ones. Follow the arrows in the download; each one now carries the whole memory to the next step.